Production / Tokyo
Create monitor

Workspace / Production

System overview

All systems operational

Global uptime 30d

0%↑ 0.04% vs last month
P95 latency 24h

0ms↓ 8ms improvement

Error rate 1h

0%Within SLO budget

Active incidents Now

0No open alerts
Request throughputLast 24 hours
8.42M requests
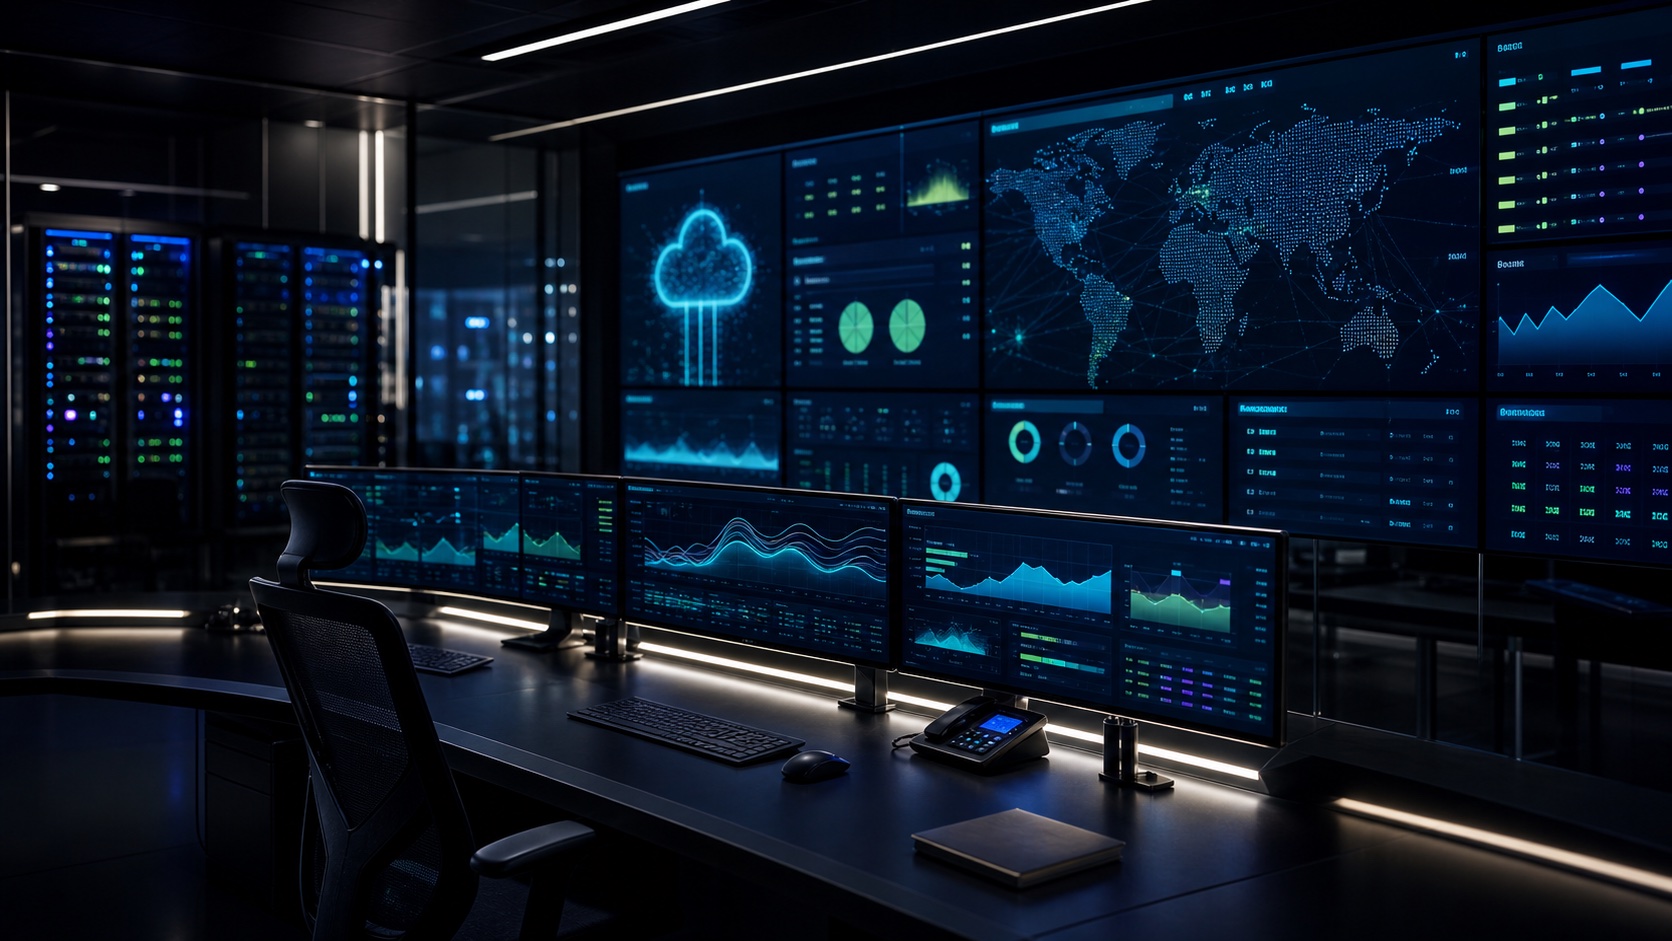
クラウド監視を表示する暗いダッシュボード

Service health

View all
  • api-gatewayap-northeast-1

    99.99%
  • checkout-serviceap-northeast-1

    99.97%
  • identity-coreGlobal edge

    100%
  • event-workerQueue elevated

    98.82%

INFRASTRUCTURE

Services & topology

EDGEGlobal CDN124 nodes
APIGateway42ms p95
COREIdentity12 pods
DATAPostgres3 replicas
ASYNCEvent bus1.2k msg/s
ServiceDeployLatencyError rateStatus
checkout-servicev2.8.1438 ms0.01%Healthy
inventory-syncv4.1.0261 ms0.04%Healthy
event-workerv1.9.30128 ms0.18%Degraded

GLOBAL STATUS / REGIONS

世界の状態を、ひと目で。

04 regions / Live
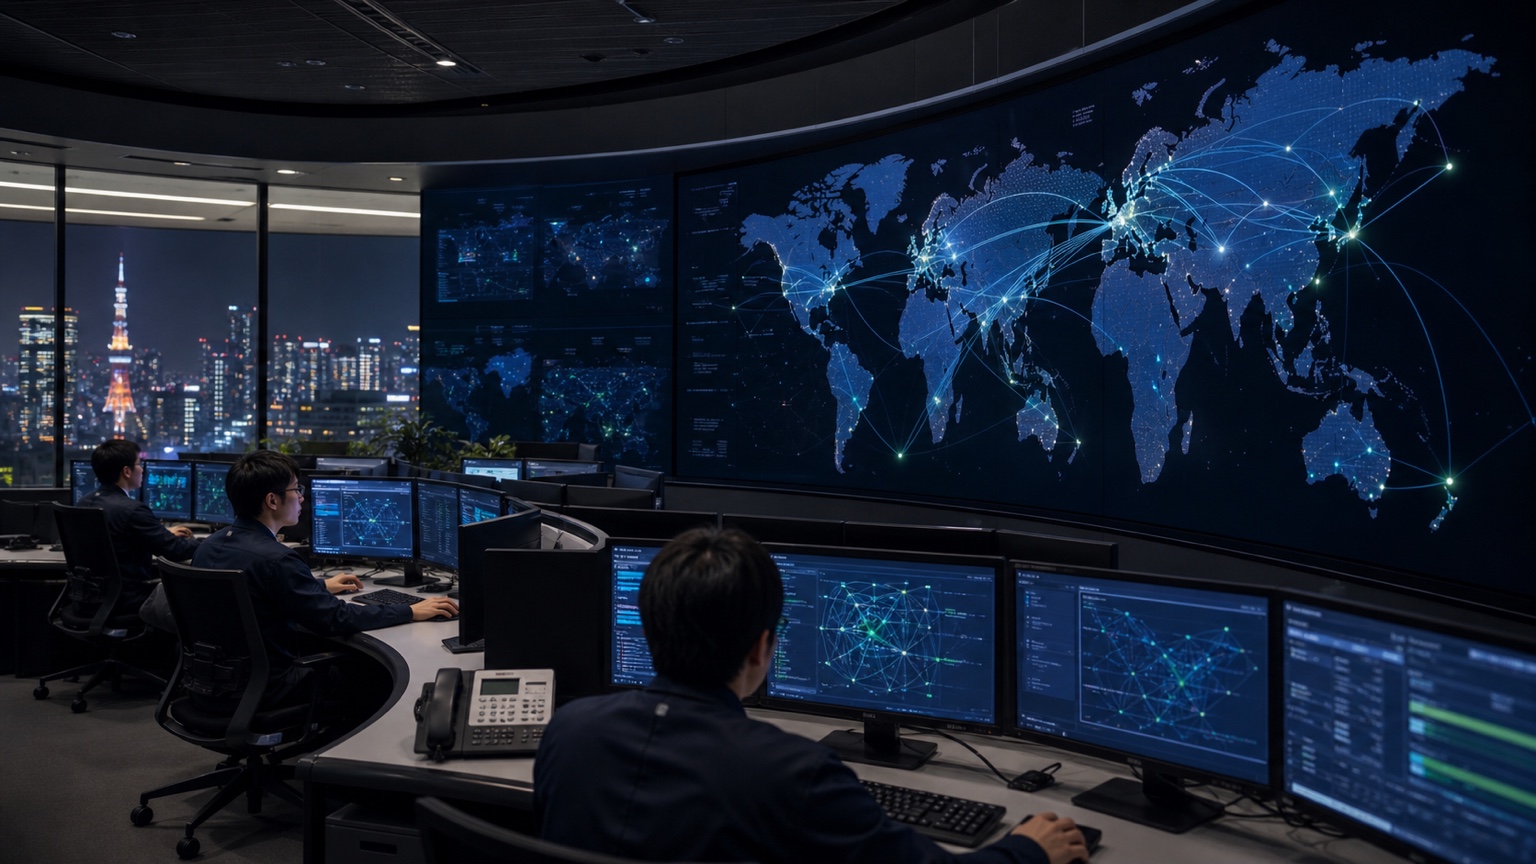
世界各地の稼働状況を監視する東京のネットワークオペレーションセンター
Traffic paths / 12:48:22 UTC

Tokyoap-northeast-1

99.99%Operational

Singaporeap-southeast-1

99.98%Operational

Frankfurteu-central-1

99.97%Operational

Virginiaus-east-1

99.91%Watching
Last sync12 sec ago

LIVE TAIL

Recent logs

12:48:22.104INFOapi-gatewayGET /v2/checkout 200 duration=38ms region=nrt
12:48:21.887INFOidentity-coretoken.refresh success user_id=7f2a…
12:48:20.612WARNevent-workerqueue.lag threshold=120s current=148s
12:48:19.042INFOcheckoutpayment.authorized provider=stripe attempt=1
12:48:18.772INFOinventory-syncbatch.completed items=842 duration=1.8s

RELEASE PIPELINE / CI-CD

変更の流れを、ひとつの画面に。

Release #4821 / Running
リリース状況を確認するクラウド運用チーム
checkout-service / v2.8.14
  1. 01
    BuildPassed · 42s
  2. 02
    Test186 checks · 2m
  3. 03
    Canary10% traffic · 4m left
  4. 04
    PromoteWaiting for approval

INCIDENT REVIEW

インシデント対応を、チームの知識へ。

INC-204 / Resolved in 18m
監視画面を見ながらインシデントを振り返る運用チーム
Review complete / Tokyo command room
  1. Latency alert firedcheckout p95 > 250ms
  2. Owner identifiedevent-worker / deploy v1.9.30
  3. Traffic recoveredrollback complete / error 0.03%
  4. Runbook updatedRB-42 / queue saturation
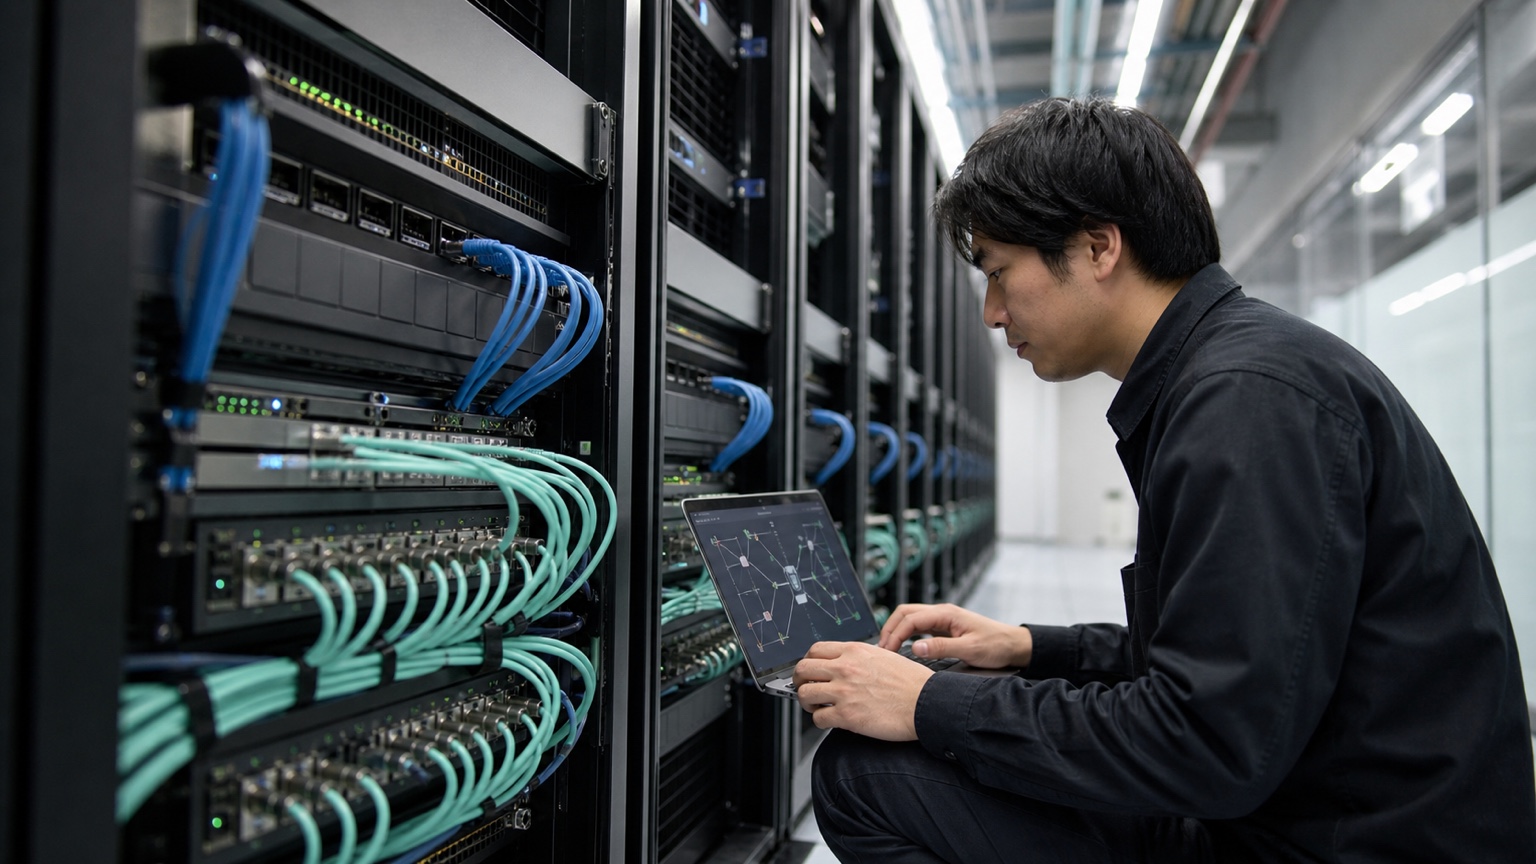
データセンターのサーバーラックを点検するエンジニア
INFRA / DATA CENTER
監視画面の前で状況を共有する運用チーム
RESPONSE / STANDUP

ALERT ROUTING / ON-CALL

必要な人へ、必要な順番で。

Queue / 03 active
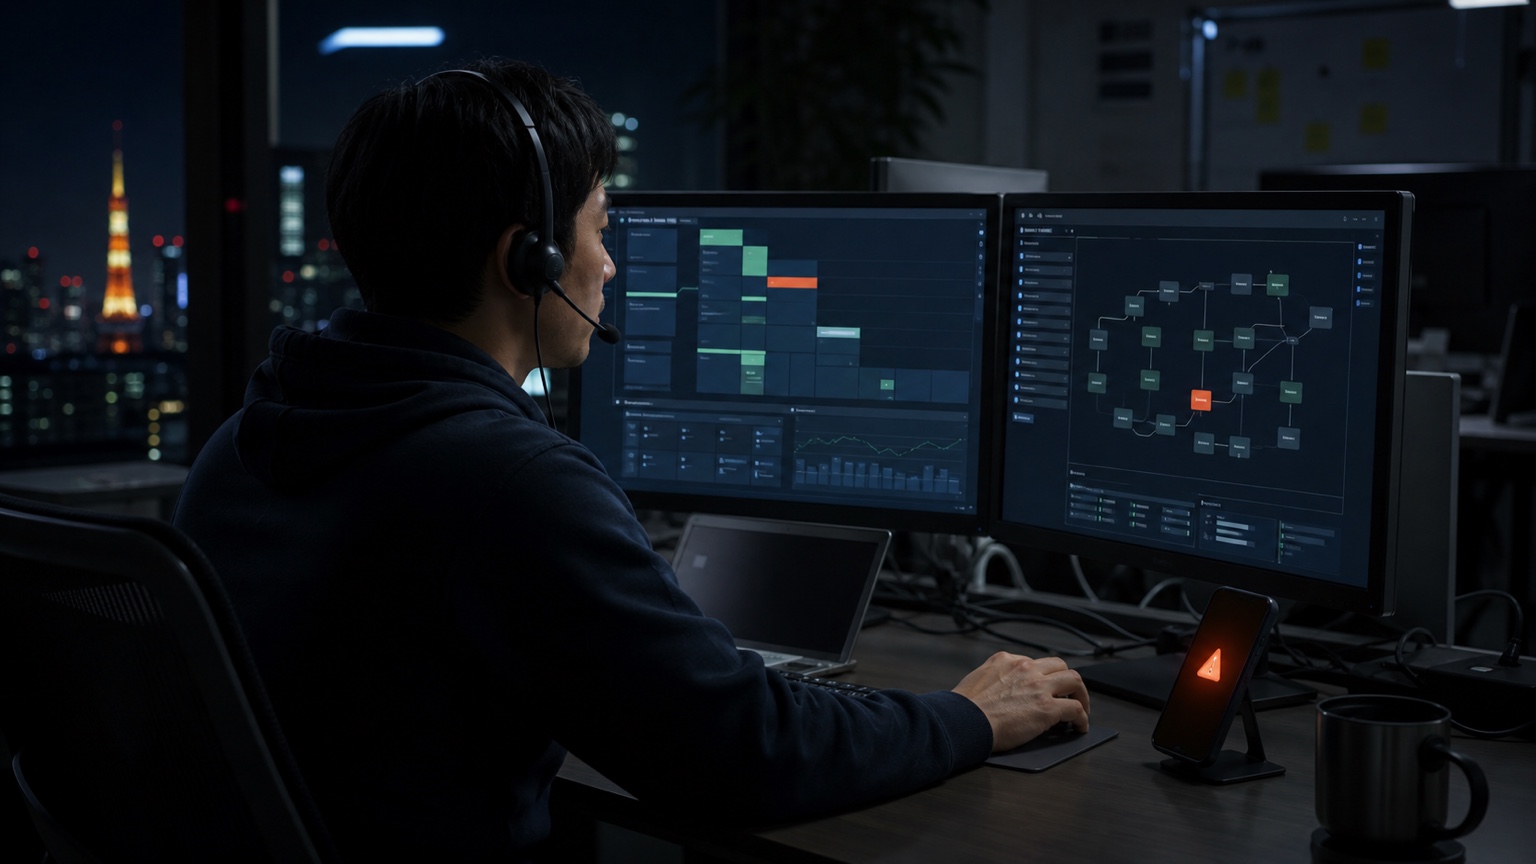
夜間のワークステーションで通知を確認するオンコール担当者
On-call / Tokyo · 02:14
P1

Checkout latencyEscalate immediately

→ SRE lead
P2

Queue saturationNotify within 10 min

→ Platform team
P3

Certificate expiryOpen next business day

→ Service owner

RUNBOOKS / AUTOMATION

よくある対応は、手順ごと自動化。

RB-42 / Queue saturation
WHENQueue lag > 120s
CHECKInspect worker health3 services
IF HEALTHYScale workers+2 pods
IF DEGRADEDPage ownerIncident INC-204
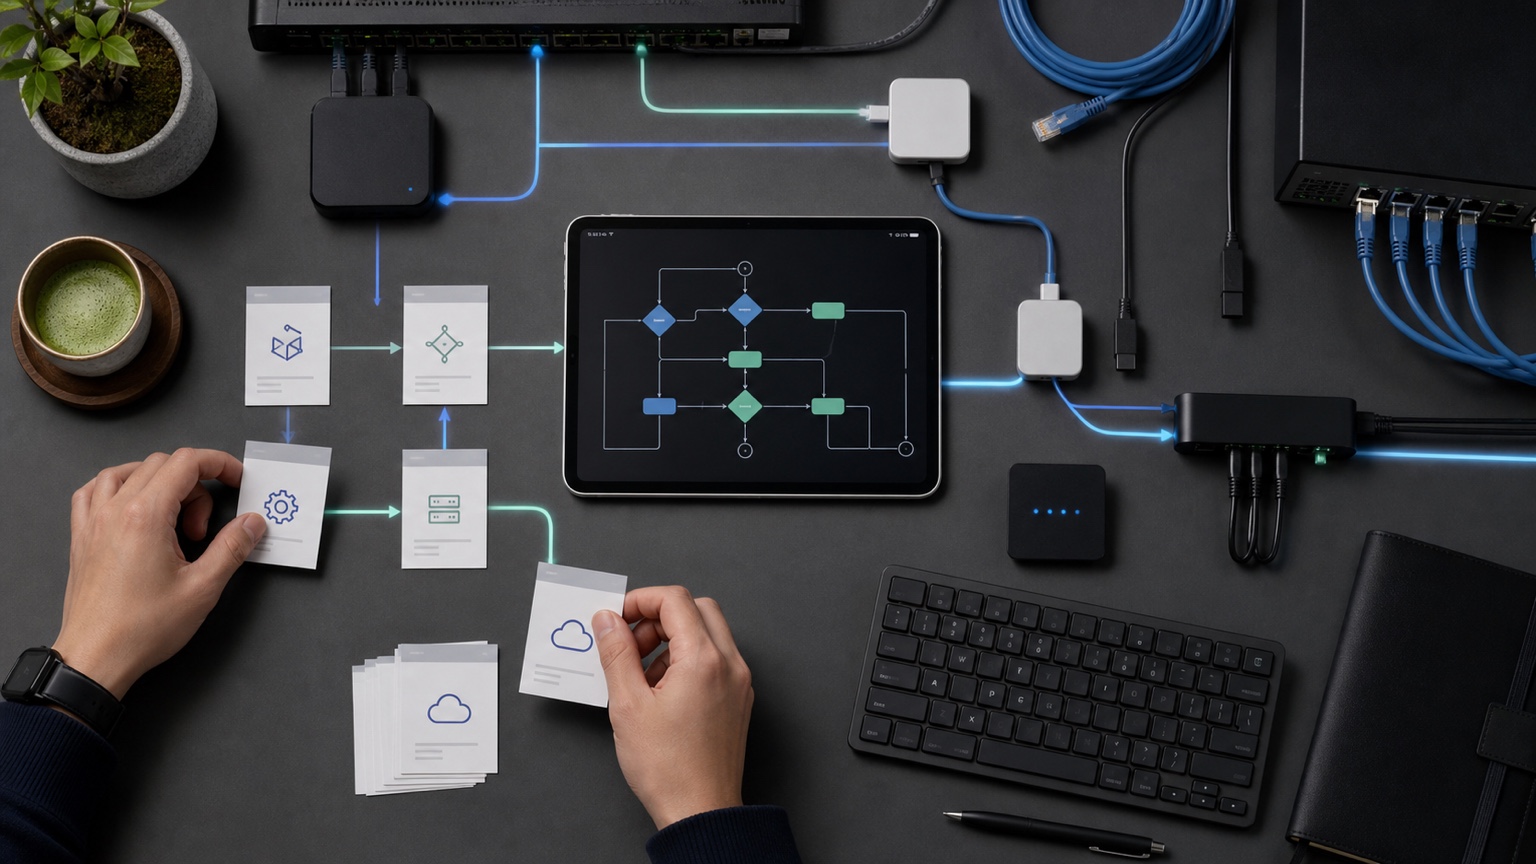
運用手順と端末を俯瞰した自動化ワークスペース
Automation run / 18s average

INTEGRATIONS / CONNECTED

いつものツールを、そのままつなぐ。

12 connectors / Healthy
サーバー接続と連携構成を確認するエンジニアリング環境
Connected stack / Production
  • SlackIncident notifications

    Connected
  • GitHubDeploy events

    Connected
  • PagerDutyOn-call escalation

    Connected
  • DatadogMetric import

    Available

RELIABILITY

SLO performance

Reporting period: 30 days
API availability99.99%

Target 99.95%+21m budget

Checkout latency99.92%

Target 99.90%+8m budget

Event delivery99.81%

Target 99.80%+2m budget

SUPPORT QUEUE / FAQ

導入前に、よくある質問。

6 answered / Support online
01どのサービスから監視を始められますか?+

まずはAPIや決済など、止まると影響が大きいサービスから始められます。現在の構成に合わせて範囲を決めます。

02既存のログ基盤と一緒に使えますか?+

はい。既存のログやメトリクスを活かしながら、必要な情報をNEXUS Opsにまとめられます。

03通知先はチームごとに分けられますか?+

重要度、サービス、時間帯ごとに担当者や通知先を分けられます。オンコールの流れも設定できます。

04導入までにどのくらいかかりますか?+

構成が決まっていれば、最初の監視は短いレビューから始められます。段階的な導入にも対応します。

05運用チーム向けのサポートはありますか?+

ダッシュボードの設計、アラートの整理、運用手順の見直しまで、チームの状況に合わせて伴走します。

06小さな環境でも相談できますか?+

もちろんです。今後の拡張を見据えながら、必要な画面と通知だけに絞って始められます。

Ready to connect your stack?15分の構成レビューで、監視の空白と導入範囲を確認します。

Schedule architecture review →